

An OOM (Out of Memory) kill is a painful incident. Once it happens, the server is killed and restarted, and the only thing left at the scene is a pile of memory metrics.
But once you start looking at those metrics, the problem often becomes confusing.
For example:
- Grafana shows high RSS, but the pprof heap `inuse_space` is much lower.
- The container is already close to its memory limit, but Go heap metrics still look fine.
So which memory metric actually decides whether a process gets OOM killed? And if these metrics do not match, how should we interpret them?
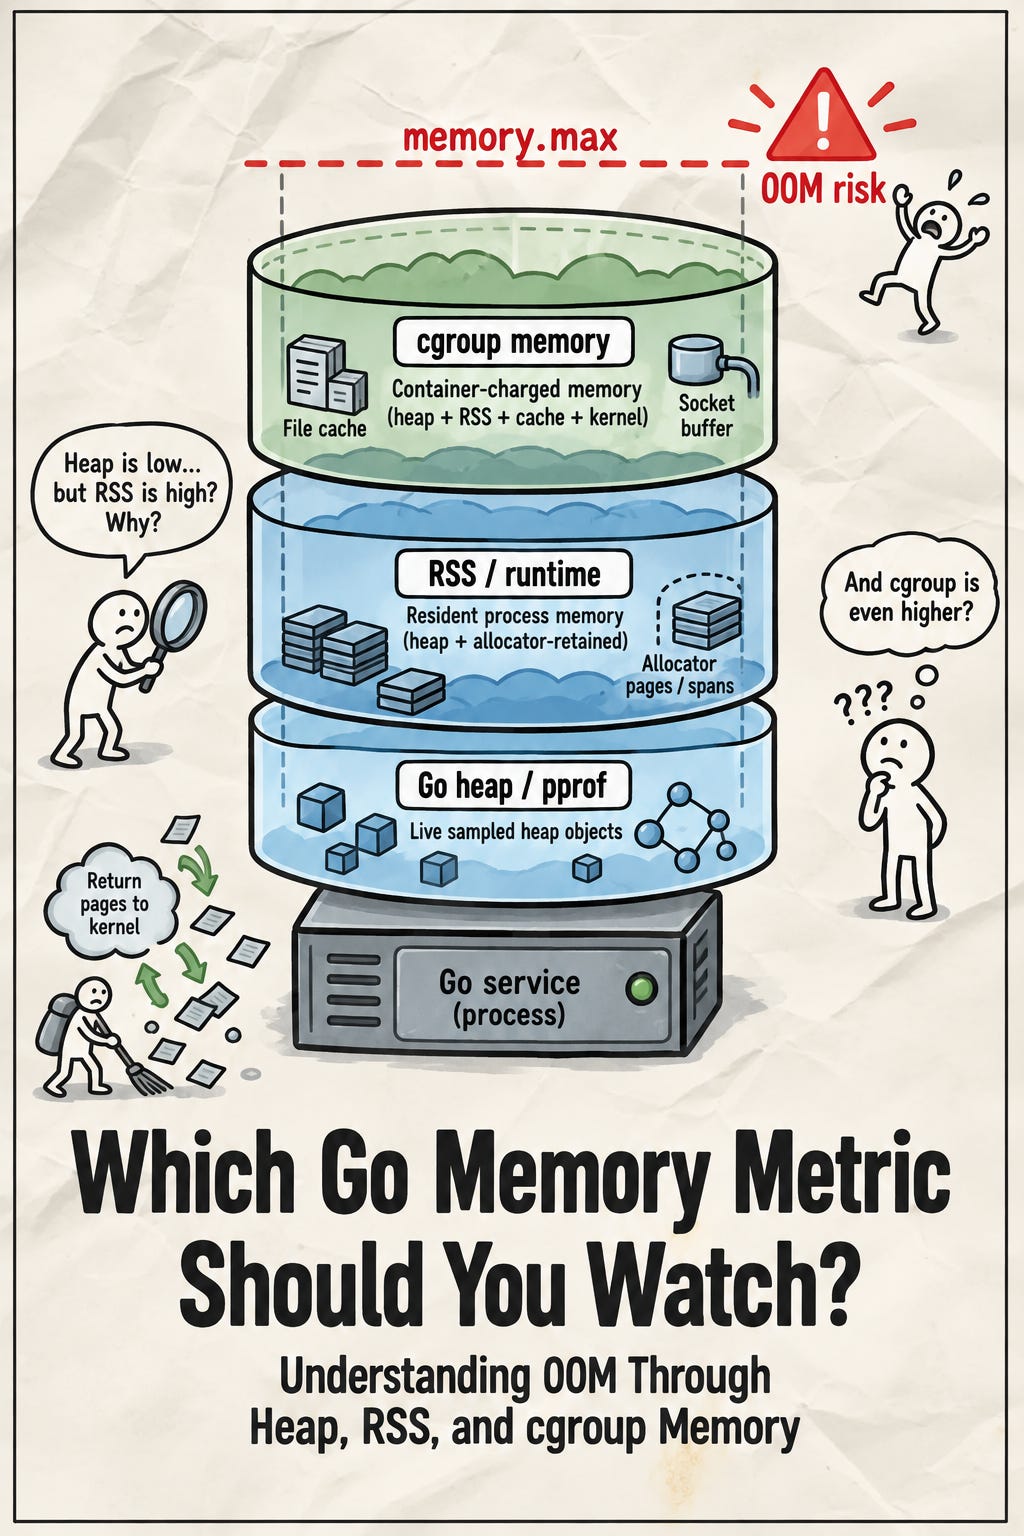
When does an OOM kill happen?
When a server runs inside a container, cgroups are used to limit the resources available to that container. For memory, cgroup v2 uses settings such as `memory.max`. If the cgroup’s memory usage reaches `memory.max` and the kernel cannot reclaim enough memory, the cgroup OOM killer may be invoked.
The key metric here is not Resident Set Size (RSS), which measures resident physical memory for a process. The key metric is cgroup memory usage. So what is the difference?
A cgroup is essentially a resource accounting and limiting mechanism for a group of processes.
For example, memory.current is the cgroup v2 memory usage metric. It means the kernel has charged this amount of physical memory tothis cgroup, which usually corresponds to a specific container in a container runtime. This includes RSS, but it may also include memory used inside the kernel on behalf of that cgroup, such as:
- file cache created when a process opens or reads files
- socket buffers and related kernel memory created for TCP connections
Therefore cgroup memory usage may be higher than RSS. Some of this memory is reclaimable, especially clean file cache. Reclaiming clean file cache is usually safe because the data can be read from disk again after a cache miss. But not all kernel memory is equally reclaimable, so a high cgroup usage number still needs to be investigated.
In cgroup v2, `memory.high` can also be configured. When cgroup memory usage goes above this threshold, the kernel puts the cgroup under reclaim pressure and may throttle it. Unlike `memory.max`, crossing `memory.high` does not directly invoke the OOM killer.
In Kubernetes or container environments, cgroup memory metrics are commonly exposed through cAdvisor Prometheus metrics:
- `container_memory_usage_bytes`:
Current cgroup memory usage. In cgroup v2, this roughly corresponds to `memory.current`.
- `container_spec_memory_limit_bytes`:
The container memory hard limit. In cgroup v2, this roughly corresponds to `memory.max`.
- `container_memory_rss`:
RSS for the container’s processes.
- `container_memory_cache`:
File cache charged to the cgroup.
- `container_memory_working_set_bytes`:
Usually calculated as usage minus `inactive_file`. It is often used as an estimate of memory that is less easily reclaimable. Kubernetes eviction logic also commonly relies on working-set-style memory metrics.
- `container_oom_events_total`:
The number of OOM events observed for the container.
Once we understand cgroups, we know that memory monitoring needs to look at both user-space process memory, such as RSS, and kernel-accounted memory, such as file cache and socket memory.
But inside the user-space process, the runtime has its own memory metrics. If we want to locate which function allocated memory, we need runtime profiling. This creates another common question: why does runtime profiling often disagree with RSS?
Why can RSS be larger than pprof heap inuse space?
In Go, it is tempting to think that the pprof heap profile represents “the memory used by the program.” But that is not quite right.
The pprof heap `inuse_space` view is about live sampled Go heap allocations. In other words, it estimates heap objects that are still live and have not been reclaimed by GC.
RSS answers a different question:
How much physical memory is currently resident for this process’s virtual address space?
The process may use memory outside live Go heap objects. This includes goroutine stacks, runtime metadata, memory allocated by C code through cgo, memory mapped through system calls, and other non-heap regions.
Suppose there is no deep recursion, no unusually large stacks, and no cgo. Should RSS then be close to heap `inuse_space`?
Not necessarily.
The reason is that when GC reclaims heap objects, Go does not necessarily return that memory to the kernel immediately. It first returns the memory to the Go runtime’s memory allocator.
At that point, pprof heap `inuse_space` may go down, but RSS may not. The missing layer is the memory allocator.
What problem does a memory allocator solve?
Start with a naive design. Suppose every Go object allocation directly asked the kernel for memory:
new object -> syscall -> OS allocates pages -> return to user space
This design has two problems.
First, system calls are expensive. If every small object allocation requires a syscall, allocation-heavy Go programs would spend too much time crossing between user space and kernel space.
Second, the operating system manages memory at a coarse granularity. A common page size is 4 KB, but a Go object may be only 16 bytes. If every small object occupied its own OS page, memory waste would be enormous.
To solve these problems, the Go runtime’s memory allocator first obtains larger chunks of memory from the OS. At that point, RSS may increase. Later, when the program allocates an object, the allocator serves that request from memory it already manages, usually using a size class that is close to the requested object size.
In simple terms, the memory allocator sits between the kernel and application objects.
It manages coarse-grained pages, divides them into smaller allocation units for different object sizes, and avoids making a syscall for every `new` object.
What do Go heap metrics mean?
Once we understand the allocator, Go runtime memory metrics become easier to read:
- `go_memstats_heap_alloc_bytes`:
Bytes of currently live Go heap objects.
- `go_memstats_heap_inuse_bytes`:
Bytes in active heap spans. A span contains multiple slots for objects.
- `go_memstats_heap_idle_bytes`:
Heap memory the runtime has obtained but that is currently in idle spans.
- `go_memstats_heap_sys_bytes`:
Heap memory obtained from the OS. This includes heap address space that may not currently correspond to resident physical memory.
- `go_memstats_heap_released_bytes`:
Idle heap memory that has been released back to the OS and has not yet been reacquired by the runtime.
- `go_memstats_alloc_bytes_total`:
Cumulative heap allocation bytes since process start.
The difference between `go_memstats_heap_inuse_bytes` and `go_memstats_heap_alloc_bytes` is important.
`heap_alloc` counts the logical size of live heap objects. `heap_inuse` counts active heap spans. A span contains slots, and those slots are tied to size classes.
For example, suppose an object is 14 bytes, but the allocator’s nearest slot size is 16 bytes. `heap_alloc` accounts for the object size, but the allocator needs a 16-byte slot to store it.
More importantly, `heap_inuse` is the total size of in-use spans. If a span has at least one live object, the span is considered in use. If a span has no live objects, it becomes idle and is counted in `heap_idle`.
heap_sys = heap_inuse + heap_idle. In theory, this can be closer to RSS than heap_alloc or heap_inuse, but it is still not the same as RSS. In practice, there are gaps: heap_idle may include heap memory that has already been released back to the OS, while heap_sys does not include non-heap memory such as stacks or cgo allocations.
With so many metrics, what should we watch during an OOM?
When an OOM happens, the first instinct is often to use pprof to find the guilty function.
pprof is useful because it can attribute memory to call stacks. For Go heap profiles, pprof commonly exposes views such as inuse_space and aloc_space.
Profiling is based on periodic sampling, so:
- `inuse_space`:
Live sampled heap allocations. The heap profile reports data as of the most recently completed GC, so it is not always a perfectly current snapshot.
- `alloc_space`:
Cumulative sampled heap allocation bytes since process start, including allocations that have already been garbage collected.
If `inuse_space` is not large, the profile may have missed the critical moment, or the issue may not be live Go heap. The next step is to check whether runtime `heap_alloc` is large.
If `heap_alloc` is large but pprof does not show a clear culprit, the heap profile may be too stale, too sampled, or collected at the wrong moment. In that case, look at memory trends over time and compare profiles taken before and during the growth.
If `heap_alloc` is also not large, then inspect the gap between runtime metrics:
- `heap_inuse - heap_alloc`:
This estimates memory dedicated to size classes but not currently holding live objects. It is an upper bound on fragmentation. If this number is large, it may indicate allocator slack or fragmentation inside active spans.
- `heap_idle - heap_released`:
This is idle heap memory that could be returned to the OS but is still retained by the runtime. If this value is large, it may indicate a recent transient heap spike or a runtime return policy tradeoff.
Finally, compare cgroup memory usage and RSS.
If RSS is not large but cgroup memory usage is high, the pressure may come from cgroup-accounted kernel memory, such as file cache, socket buffers, or other kernel structures.
A useful mental model is to split memory metrics into three layers:
- application layer:
Use pprof to identify which call stacks are responsible for live or cumulative Go heap allocations.
- process and runtime layer:
Use RSS and Go runtime metrics to understand the whole process footprint and allocator state.
- kernel and cgroup layer:
Use cgroup metrics to understand what the kernel has charged to the container, including RSS and kernel-accounted memory.
Once we understand these layers, it becomes clear why the memory allocator matters. A poor allocator design, or a workload pattern that interacts badly with the allocator, can keep RSS high even when live heap is low.
So what makes a good memory allocator?
What challenges does a memory allocator need to solve?
A good memory allocator mainly balances three goals:
- allocation latency:
Allocating a new object must be fast and must not burn too much CPU.
- fragmentation:
The allocator should avoid wasting memory in a way that makes free space hard to reuse or return to the OS.
- return policy:
After GC frees objects, the allocator must decide when and how to return memory to the kernel. It needs to balance performance against OOM risk.
We can use the Go runtime allocator as an example.
How does the Go memory allocator reduce allocation latency?
After the allocator obtains memory from the kernel, it needs data structures to manage that memory. At the same time, Go allocations happen concurrently across goroutines executing on different Ps and OS threads. If every allocation had to contend on one global allocator lock, allocation latency would suffer.
To avoid this, Go uses a hierarchy of allocator structures. There is per-P allocation cache for fast local allocation, and more global allocator structures are used only when the local cache has no suitable span or when an allocation is large.
The data structure design matters too. Go divides small object allocation into size classes such as 8 bytes, 16 bytes, 24 bytes, 32 bytes, and so on. Each size class manages slots of a fixed size. For example, allocating a 10-byte object will use a 16-byte slot.
This narrows the search space and makes allocation faster.
But how does the allocator find an available slot inside a span?
At a simplified level, object slots are like array entries, and each slot has an index. A bitmap records which slots are available. For example, in a simplified free bitmap, `11111110` can mean that all slots except index 0 are free.
Finding a free slot then becomes a bit operation. The allocator can find the lowest set bit:
idx = 0;

while (free_bitmap > 0) {

    if (free_bitmap & 1 == 1) return idx;

    free_bitmap >>= 1;

    idx++;

}
Real Go internals use `allocBits` and `allocCache`. In Go’s implementation, `allocCache` stores the complement of `allocBits`, shifted so that the lowest bit corresponds to `freeindex`. This makes it possible to use a count-trailing-zero operation to quickly find the next free slot.
For explanation, imagine two 8-bit chunks:
`11111110 11000000`
Suppose:
`freeindex = 5`
`allocCache = 1110110`
Then allocation works conceptually like this:
1. Find the lowest available bit in `allocCache`. Suppose the offset is 2.
2. Add that offset to the base `freeindex`, so the real slot index is `5 + 2 = 7`.
3. Update `freeindex` and refresh `allocCache` from the next position.
The real implementation is more subtle, but the core idea is simple: represent slot state compactly and use CPU-friendly bit operations to find the next free object quickly.
What fragmentation problems can the Go allocator run into?
Fragmentation can be divided into two types: internal fragmentation and external fragmentation.
Internal fragmentation happens when the object is smaller than the slot allocated for it. For example, if a 17-byte object is placed into a 24-byte slot, the remaining 7 bytes are wasted.
Size classes make allocation faster and keep different object sizes organized, but the cost is that objects are rounded up to the nearest slot size. This creates controlled internal fragmentation.
Struct field layout can also make internal fragmentation worse.
For example:
type Test struct {
    A int8
    B int32
}
It looks like this struct should be 5 bytes: 1 byte for `A` and 4 bytes for `B`. But on typical architectures, it will be 8 bytes because of struct padding.
The reason is alignment.
When the CPU loads data from memory, hardware usually prefers certain alignment boundaries. For example, a 4-byte load is most natural when it starts at an address that is a multiple of 4.
If an address is 0, 4, 8, or 12, then a 4-byte value is aligned. Aligned access is usually simpler and faster for the CPU.
In the `Test` struct, padding is inserted after `A` so that `B` starts at an aligned address. Without padding, `B` might cross two machine-word-sized chunks, forcing extra work to assemble the value.
A better field order can make padding more compact:
type Bad struct {
    a int8
    b int64
    c int8
}

// 24 bytes on a typical 64-bit platform

type Better struct {
    b int64
    a int8
    c int8
}

// 16 bytes on a typical 64-bit platform
More compact padding can keep an object from growing into the next size class, which reduces internal fragmentation.
External fragmentation is different. It means free space exists, but it is scattered in a way that makes it difficult to reuse or return to the kernel.
There are two related cases:
- Free space across pages may add up to a large amount, but the allocator cannot use it for the allocation it needs.
- The kernel reclaims memory at page granularity. If a page still contains a few live slots, the whole page cannot be returned.
Size class segregation helps because objects of very different sizes are not mixed randomly in the same memory region. That avoids arbitrary holes that are hard to reuse.
But object lifetimes are still unpredictable. Slots are not freed in a neat order. A page may have only a few live objects left, but those live objects keep the entire page from being returned to the kernel.
One way to solve this is compacting GC. During GC, the runtime can move live objects together so scattered live objects become contiguous. This can make it easier to release whole pages.
But compacting GC is complex. Moving objects increases GC work, affects pointer handling, and can add CPU overhead. Go currently uses a non-moving GC, so it needs other mechanisms for deciding when and how to return memory to the kernel.
How does the Go allocator return memory to the kernel?
The Go runtime has a background scavenger. It releases idle heap pages back to the kernel in the background.
This background process balances two goals:
- RSS footprint:
Keep resident memory lower to reduce OOM risk.
- allocation latency:
Avoid releasing memory so aggressively that the runtime must repeatedly reacquire pages from the OS.
Therefore, the scavenger is not just a simple time-based trigger or a single-threshold mechanism. It uses runtime policy to balance memory footprint and allocation performance.
How memory is released also matters. A common system call used for this purpose is `madvise`.
`madvise` tells the kernel that the program no longer needs the contents of a virtual memory range. The physical memory backing that range may be reclaimed, but the virtual address range remains reserved so the runtime can reuse it later.
There are two common modes:
- `MADV_DONTNEED`:
The kernel can discard the physical pages promptly, so RSS usually drops faster.
- `MADV_FREE`:
The kernel may lazily reclaim the pages, often only under memory pressure. RSS may stay high for longer.
The benefit of `MADV_FREE` is that if the allocator reuses the memory before the kernel reclaims it, the reuse may avoid a page fault. That can improve allocation latency.
Go used `MADV_FREE` by default on Linux starting in Go 1.12, but many users found the resulting RSS behavior confusing and suspected memory leaks(https://go-review.googlesource.com/c/go/+/267100). Starting in Go 1.16, Linux defaults back to `MADV_DONTNEED`, so RSS more closely reflects memory that is still physically resident.
If you explicitly want the Linux runtime to use `MADV_FREE` instead of `MADV_DONTNEED`, set:
GODEBUG=madvdontneed=0This improves some allocation behavior, but RSS will usually drop only when the OS is under memory pressure.